Ph.D. Student in Computer Science

Yubo Wang 王钰博

I train and evaluate large language models: post-training for reasoning, robust benchmarks, and foundation models for coding agents.

University of Waterloo · Vector Institute · TIGER-Lab · Waterloo, Canada

  • LLM Post-Training & Reasoning
  • Evaluation & Benchmarks
  • Coding Agents & Mid-Training
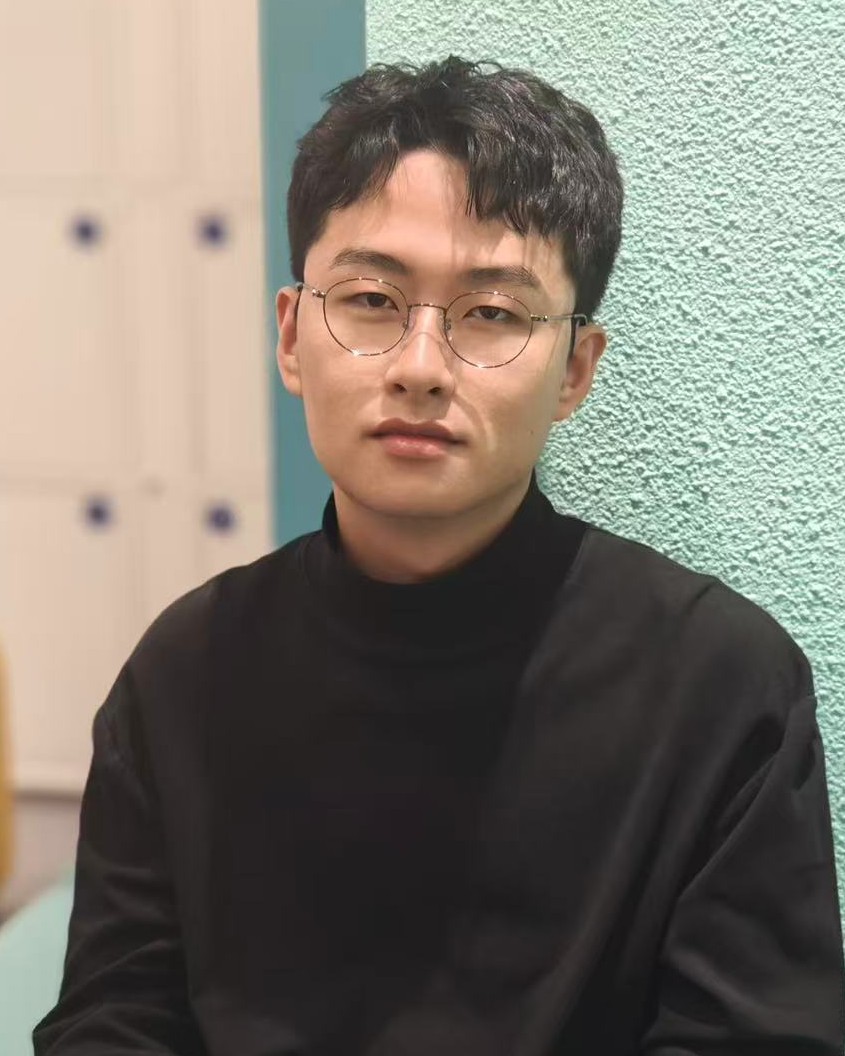
Portrait of Yubo Wang

About

I am a Ph.D. student in Computer Science at the University of Waterloo, advised by Prof. Wenhu Chen in TIGER-Lab, and I am affiliated with the Vector Institute. I am currently a Student Researcher at Google Cloud AI Research, working on automated research methods. Before Waterloo, I was an Applied Scientist at Tencent Smart Healthcare (Apr 2021 – Aug 2023), and I have been working with TIGER-Lab since 2023. I received my M.S. in Computer Science from UC Davis and my B.Eng. in Computer Science from Chu Kochen Honors College, Zhejiang University. From June to December 2025 I was a Research Intern at MiniMax, working on pre-training and mid-training for the MiniMax-M2 series.

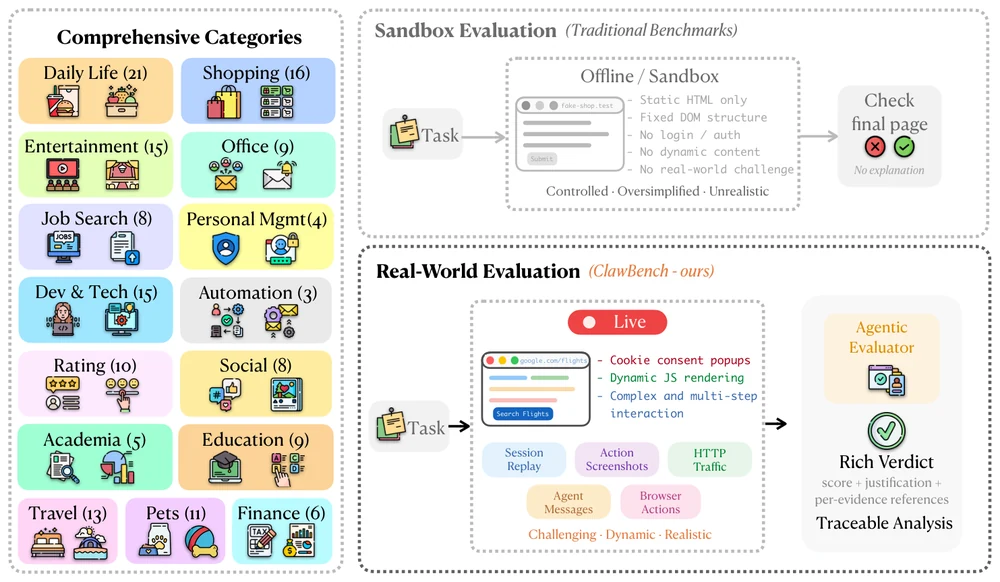
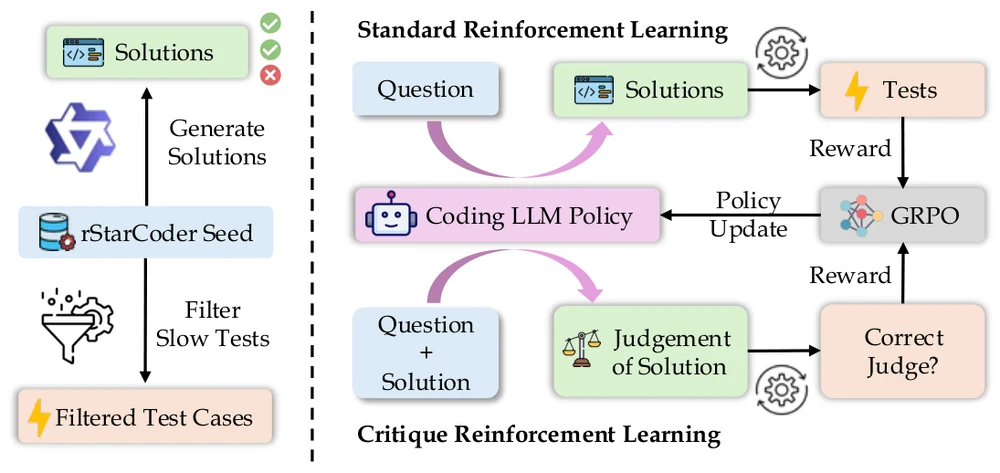
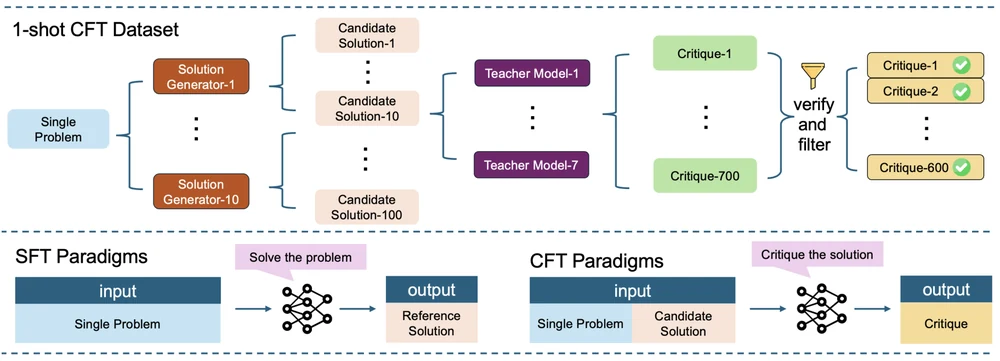
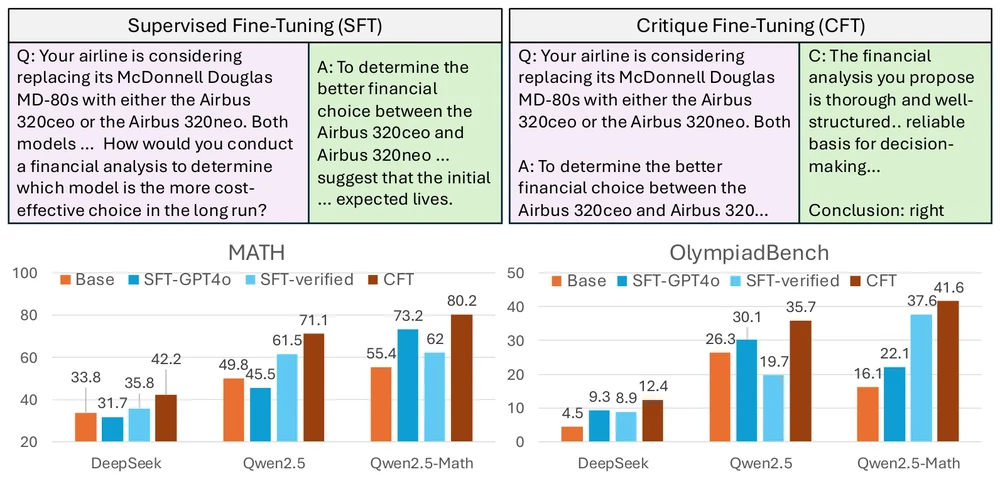
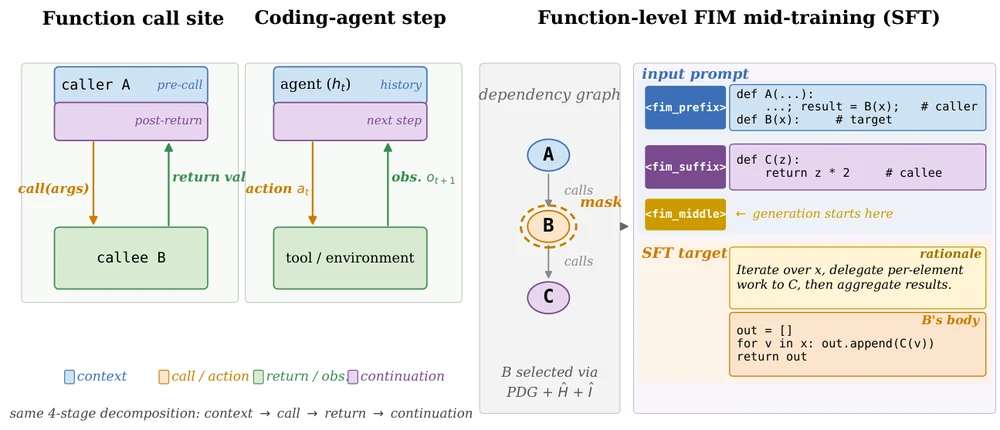
My research asks how to make LLMs both more capable and more measurable. I work on post-training for reasoning (Critique Fine-Tuning teaches models to critique rather than imitate, and works even with a single training problem), evaluation (MMLU-Pro has become a standard benchmark for frontier models; ClawBench tests agents on live websites), and foundation models for coding agents (function-aware fill-in-the-middle mid-training).

News

  1. Started as a Student Researcher at Google Cloud AI Research, working on automated research methods.

  2. ClawBench is accepted to Findings of EMNLP 2026.

  3. Released Function-Aware FIM Mid-Training for coding-agent foundation models, with code, data and models.

  4. RewardHarness is accepted to COLM 2026.

  5. The MiniMax-M2 technical report is out; I contributed as a research intern at MiniMax.

  6. Released ClawBench: 153 everyday online tasks on 144 live websites for AI agents.

  7. Critique-Coder is accepted to ICLR 2026.

  8. MMMU-Pro is featured in Google's Gemini 3 launch (Gemini 3 Pro scores 81%).

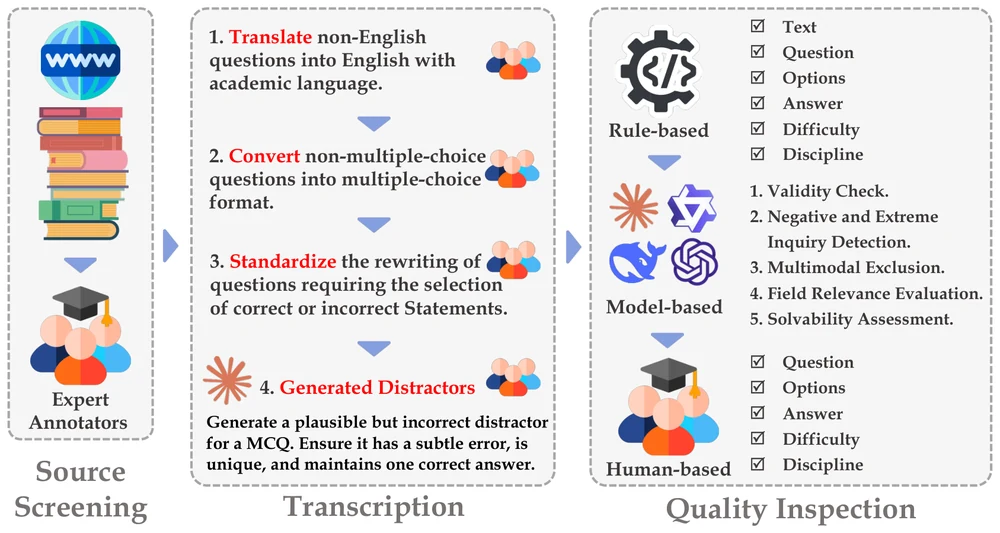
  9. SuperGPQA is accepted to NeurIPS 2025 (Datasets & Benchmarks).

  10. One-Shot CFT is accepted to EMNLP 2025 (Main).

  11. Critique Fine-Tuning and ScholarCopilot are accepted to COLM 2025.

  12. MMMU-Pro and MAmmoTH-VL are accepted to ACL 2025 (Main).

  13. MEGA-Bench is accepted to ICLR 2025.

  14. MMLU-Pro is accepted to NeurIPS 2024 (Datasets & Benchmarks) as a Spotlight, and LLM-AMT is accepted to Findings of EMNLP 2024.

  15. Released MMLU-Pro; it was adopted as a core benchmark of the Hugging Face Open LLM Leaderboard v2.

Affiliations & experience

Publications

15 papers, 8 marked Selected. * equal contribution · † core contributors · Full list on Google Scholar.

2026

2025

COLM 2025Selected

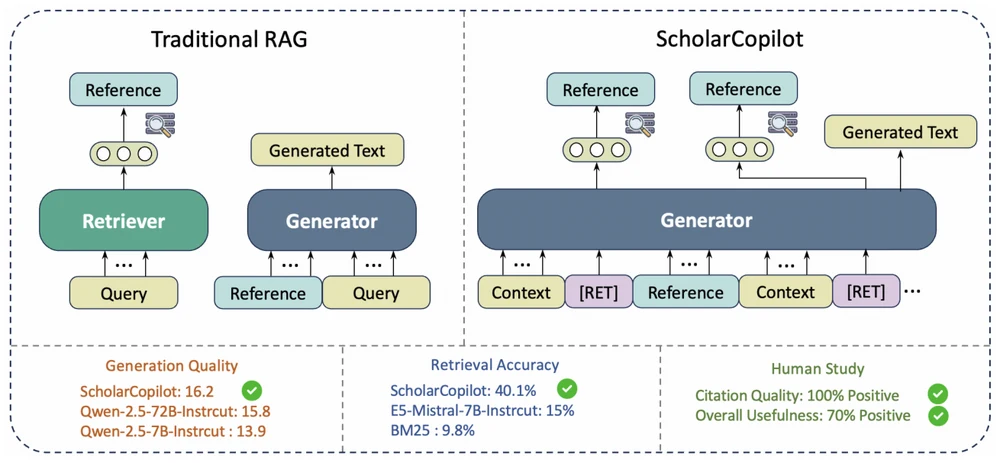
ScholarCopilot: Training Large Language Models for Academic Writing with Accurate Citations

Yubo Wang†, Xueguang Ma†, Ping Nie, Huaye Zeng, Zhiheng Lyu, Yuxuan Zhang, Benjamin Schneider, Yi Lu, Xiang Yue, Wenhu Chen†

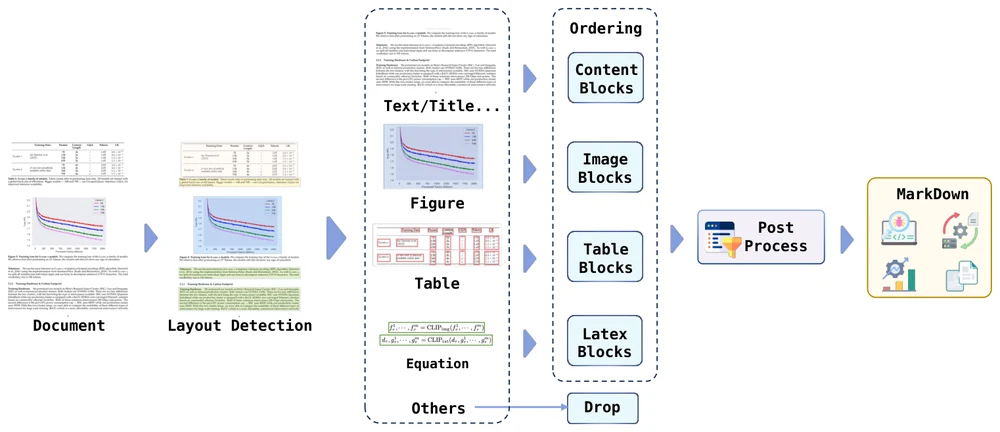
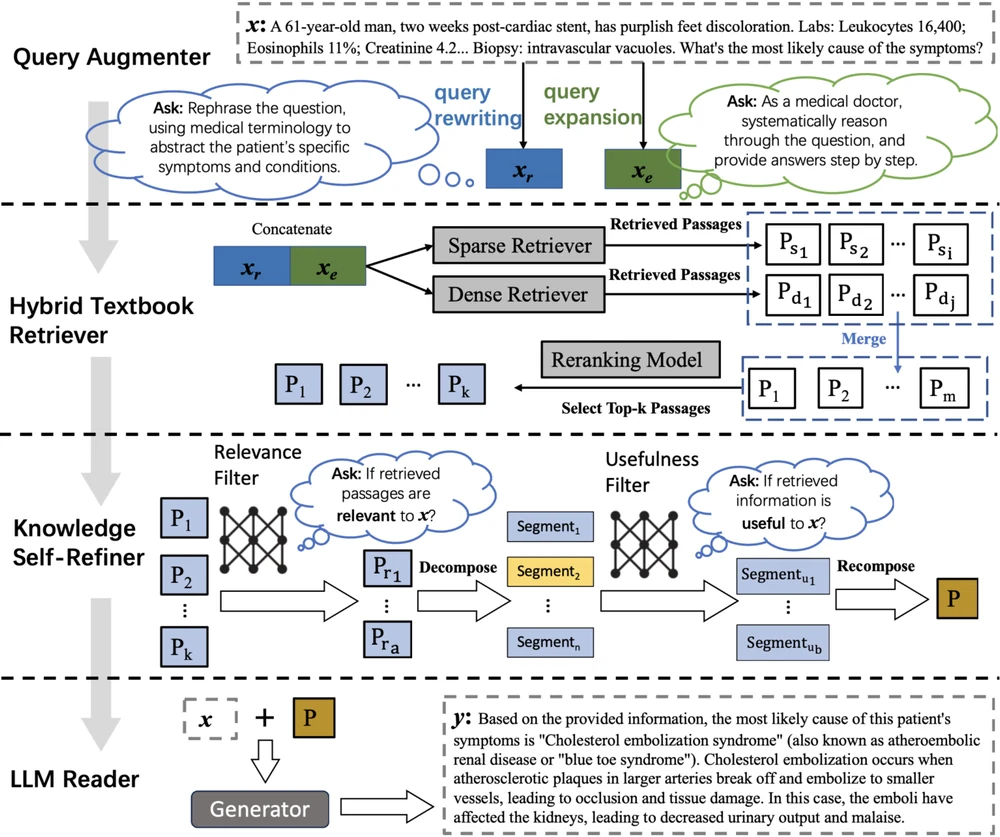
Fine-tunes Qwen2.5-7B on 500K arXiv papers to emit a [RET] token that retrieves citations mid-generation, reaching 40.1% top-1 citation retrieval accuracy versus 15.0% for E5-Mistral-7B.

2024

Experience

Education